Protecting Patient Privacy in a Multimodal World
Building AI-ready healthcare data without compromising PHI, with the founder of Glendor.
Guest
Julia Komissarchik
Founder & CEO, Glendor
Host
Muhammad Atif
CTO, PureLogics
Runtime
35 minutes
Video and audio

Watch the full conversation
Recorded for Better Health Tech. Also available on Spotify and wherever you listen.
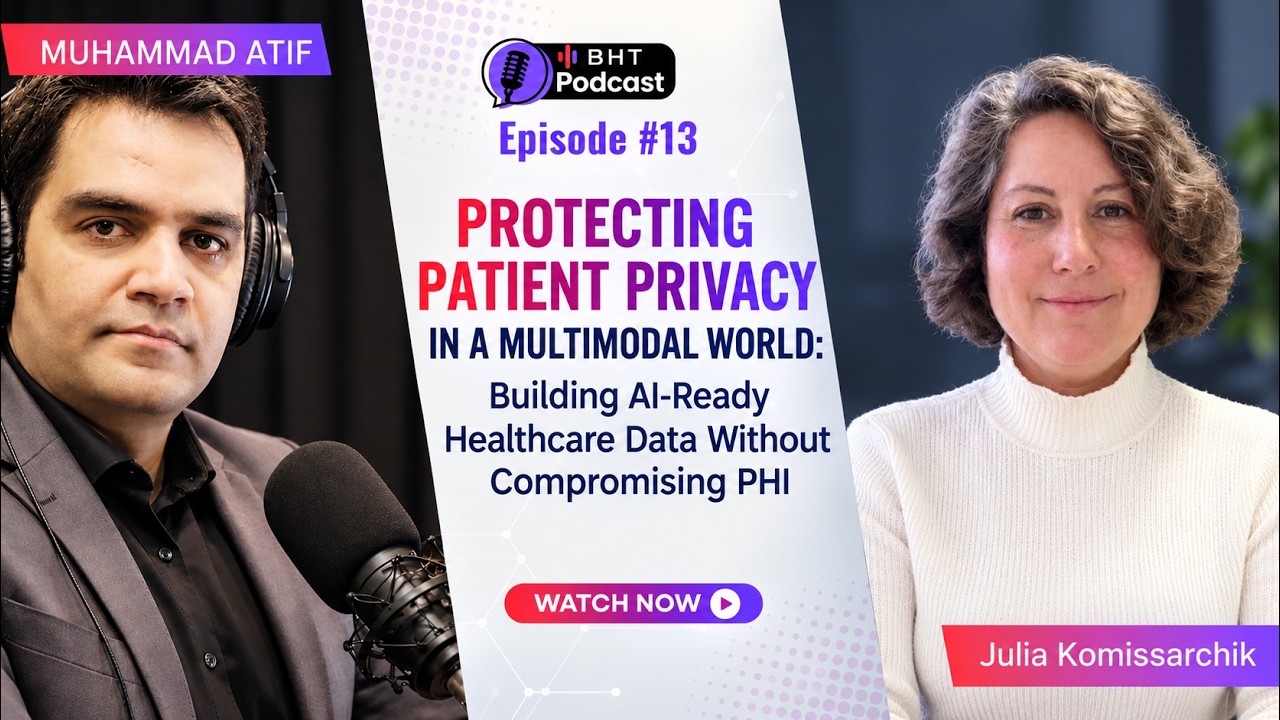
AI wants every image, scan and recording. The patient behind them still has to stay private.
Julia Komissarchik spent years in AI research, earning ten U.S. patents, before founding Glendor in 2017. Glendor detects and removes protected health information (PHI) from healthcare data at the source, inside the customer’s own environment, before that data is shared or used to train AI.
In this episode she and Muhammad Atif work through the question every healthcare AI team now faces: how do you use richer data, from medical images and pathology slides to screenshots, audio and video, without exposing the patient behind it? The answer shapes what data you can share, what your models can learn from and how much risk you carry.
What the episode covers
- How Julia moved from AI research to founding Glendor
- Why multimodal data changes the privacy problem
- Where PHI hides in ways even experienced compliance teams overlook
- How PHI Detector and PHI Sanitizer work together
- What at-source de-identification means in practice
- Balancing privacy protection with data utility
- Why on-premises and private cloud deployment matter in healthcare
- Whether HIPAA and GDPR are keeping pace with multimodal AI
Episode at a glance
Guest
Julia Komissarchik
Role
Founder & CEO, Glendor
Host
Muhammad Atif, CTO, PureLogics
Series
Better Health Tech, episode 13
Topic
Patient privacy, PHI de-identification, multimodal healthcare data
Runtime
About 35 minutes
Inside the episode
Chapter markers follow the recording plan. Confirm them against the final cut before you paste them into the YouTube description.
Opening
Has protecting healthcare data become harder as AI has become smarter?
From AI research to founding Glendor
Ten patents in AI, and the gap in healthcare data she chose to build around.
Why multimodal data changes the privacy problem
PHI no longer lives only in text fields. It hides in pixels, slides and recordings.
How at-source PHI detection works
PHI Detector, PHI Sanitizer, and why removal happens before data moves.
Balancing privacy with data utility
When over-sanitizing data starts to hurt model accuracy and research validity.
On-premises and private cloud deployment
Why sensitive data should never have to leave a customer-controlled environment.
Providers, researchers and governance teams
Different priorities, a common thread, and the most common dataset mistake.
Regulation and advice for founders
HIPAA, GDPR, what comes next, and when privacy belongs on the roadmap.
Rapid-fire round
Short answers, asked of a founder and CEO.
Where PHI hides in multimodal data
Six data types Atif puts to Julia: where patient information turns up in each one, and why text-based de-identification is not enough.
Medical images
Names, dates and record numbers in image metadata or burned into the pixels themselves.
Pathology slides
Labels, barcodes and handwritten notes captured alongside the tissue in a digitised slide.
Ophthalmology data
Retinal and eye imaging that can carry device overlays and patient details on screen.
Screenshots
Captured EHR and system screens where identifiers sit in plain view next to clinical data.
Audio
Recorded consultations where names, dates and other identifiers are simply spoken aloud.
Video and photographs
Faces, wristbands, documents and other identifying details caught in the frame.
Muhammad Atif, host of Better Health Tech and CTO at PureLogics
Three things to take into your next AI project
Protect data at the source
Detect and remove PHI inside your own environment, before data is transferred, shared or used to train a model. Cleaning it up afterwards is the risky path.
Multimodal data needs multimodal protection
Images, slides, screenshots, audio and video each carry their own privacy risk. A tool built for text fields will not catch PHI in pixels or speech.
Privacy and AI strategy are one decision
Decide early what detail a dataset must keep to stay useful, and build de-identification into the roadmap before the first model, not after.
Julia Komissarchik
Founder and Chief Executive Officer, Glendor
Julia founded Glendor in 2017 after years in AI research, during which she was awarded ten U.S. patents in artificial intelligence.
Glendor builds PHI Detector and PHI Sanitizer, which find and remove protected health information across multimodal healthcare data. They run on premises or in a private cloud, so sensitive data never leaves the customer’s control. Glendor works with healthcare providers, life sciences organizations, researchers, AI teams and privacy leaders.
Muhammad Atif
Chief Technology Officer, PureLogics
Atif hosts Better Health Tech, where he talks to the people building healthcare technology about what actually ships and what actually gets used. At PureLogics he leads custom healthcare and enterprise engineering work.
His interest across the series runs through this episode too: whether the data behind a healthcare system can be trusted as much as the system itself.
Why this episode matters
Most healthcare AI conversations focus on the model. This one goes underneath it, to the data: what it contains, who it can identify and whether it can be used safely. If your team is preparing images, recordings or records for AI, the privacy decisions are yours to make before the data moves.
The rapid-fire round
Eight questions at the end of the episode, asked of a founder and CEO who spends her days on patient data.
- Cloud-only or on-premises?
- Structured data or multimodal data, which is harder to protect?
- The most underestimated source of PHI leakage?
- One emerging technology privacy leaders should watch?
- One common misconception about de-identification?
- One book you recommend to healthcare AI founders?
- One mistake first-time healthcare AI founders make with patient data?
- One privacy-preserving healthcare tool you wish already existed?
Questions people ask about this episode
What counts as PHI?
Protected health information: anything that can identify a patient alongside their health data, such as names, dates, record numbers, faces or voices. In multimodal data it can sit inside an image, a slide label or a recording.
What is de-identification?
Removing or masking the information that ties data back to a specific patient, so it can be shared or used for research and AI with far less privacy risk.
What does at-source de-identification mean?
Detecting and removing PHI inside the organization’s own environment, before the data is transferred, shared or used to train a model.
Why is multimodal data harder to protect?
Identifiers are not only in text fields. They appear in image pixels, burned-in annotations, screenshots and spoken words, which text-based tools were never built to catch.
Does de-identification make data less useful?
It can, if it removes more than it needs to. The episode covers how teams keep the detail that matters for research and model training while still protecting patients.
Who should watch this episode?
Healthcare AI founders, data and research teams, and privacy and compliance leaders preparing multimodal data for collaboration or model training.
Building something in healthcare worth talking about?
Better Health Tech features the people shipping real healthcare technology. Tell us what you are building.